Table Designer tab - Indexes
On the Indexes tab, you can create, modify, and delete indexes to optimize query performance.
Indexes grid
The Indexes grid shows existing indexes and lets you add or remove them and view their details.
Add indexes
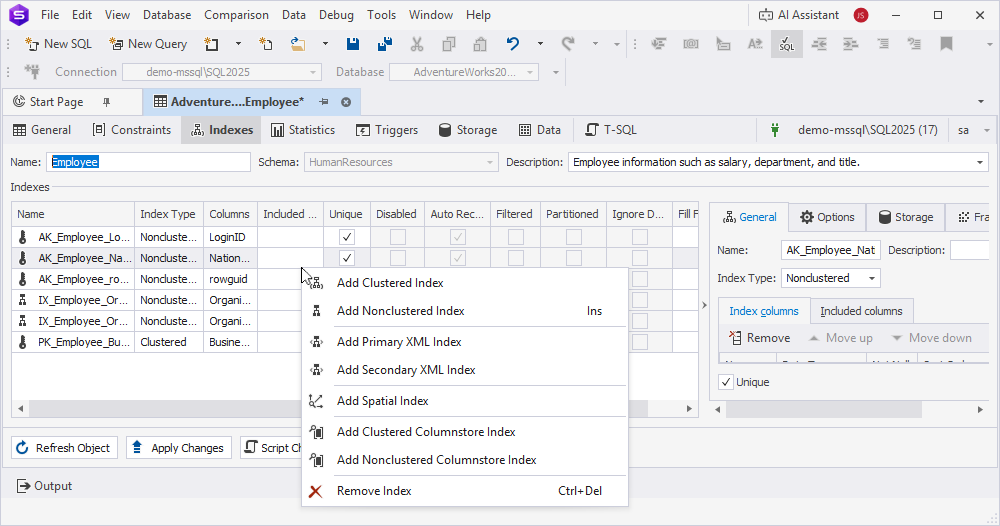
To add an index, right-click the Indexes grid and select one of the following options:
- Add Clustered Index – Creates a clustered index with the unique option enabled.
- Add Non-Clustered Index – Creates a nonclustered index. Alternatively, press Ins.
- Add Primary XML Index – Creates a primary XML index.
- Add Secondary XML Index – Creates a secondary XML index.
- Add Spatial Index – Creates a spatial index.
- Add Clustered Columnstore Index – Creates a clustered columnstore index.
- Add Nonclustered Columnstore Index – Creates a nonclustered columnstore index.
Note
To create a secondary XML index, first, you must add the primary XML index on the XML type column.
Note
The following prefixes are added to the index name by default:
IDX– Indicates a nonclustered index.UK_– Indicates a clustered index with the unique option enabled.PMXL– Indicates a primary XML index.SMXL– Indicates a secondary XML index.SPX– Indicates a spatial index.CSX– Indicates a clustered and nonclustered columnstore index.
Remove indexes
To remove an index, select it in the Indexes grid, right-click it, then select Remove Index. Alternatively, press Ctrl+Del.
View index details
The Indexes grid displays the following index details:
- Name – Specifies the index name.
- Index Type – Specifies the index type such as clustered, nonclustered, primary XML, or secondary XML.
- Included columns – Specifies the columns stored in a nonclustered index.
- Unique – Prevents duplicate values in the indexed column. This property is usually used for primary keys and unique constraints.
- Disabled – Indicates whether the index is turned off. The index remains in the database and can be re-enabled when needed.
- Filtered – Indicates whether the index uses a
WHEREclause to include only specific rows. - Partitioned – Indicates whether the index is split into smaller, manageable partitions based on a specified column.
- Auto Recompute Statistics – Indicates whether the index statistics are automatically updated when significant data changes occur.
- Ignore Duplicates – Indicates whether the duplicate values are ignored.
- Fill Factor – Specifies how much space is left free in index pages to allow for future inserts.
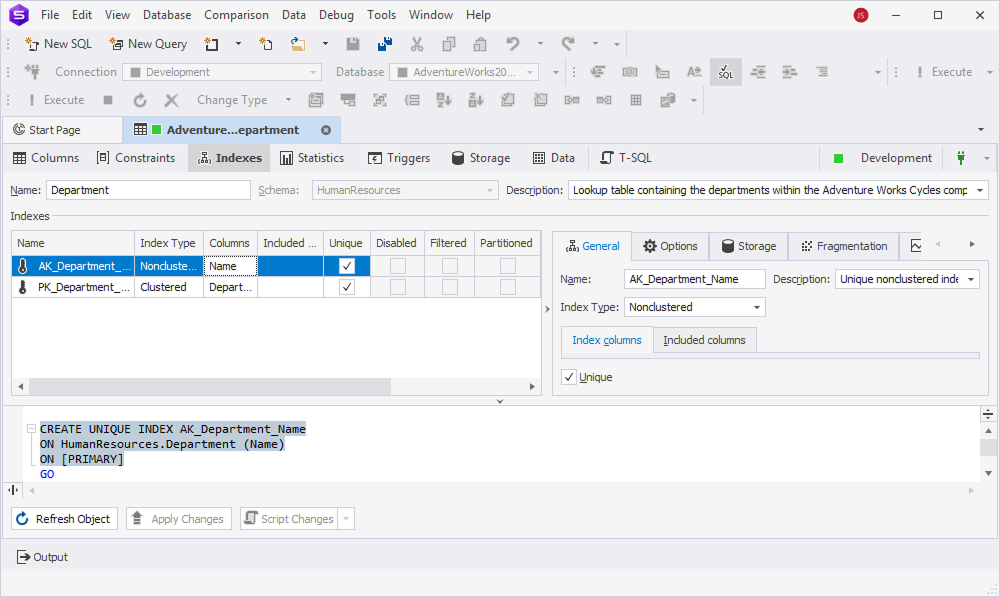
When you select the index in the Indexes grid, it is also highlighted in the T-SQL preview pane.
Index detail panel
You can configure additional index properties in the detail panel.
The properties can be grouped into the following categories:
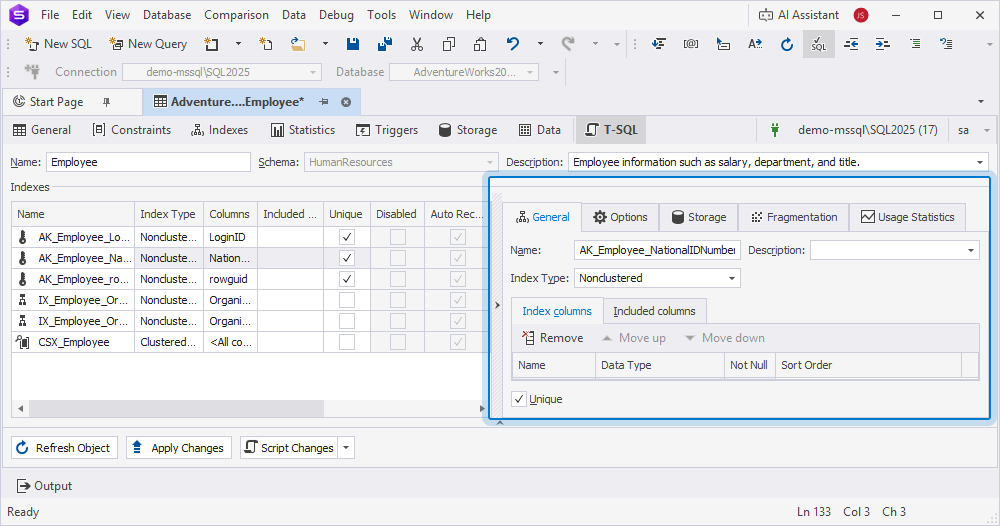
- General – Specifies the index name, description, indexed and included columns, and index type. You can remove or sort indexed columns and specify nullability and uniqueness settings.
- Options – Defines the options to customize the default behavior of indexes.
- Storage – Defines how and where the index is stored within the database.
- Fragmentation – Measures how scattered the index pages are on the disk.
- Usage Statistics – Indicates how often the index is used in queries.
General
The following table describes the general properties.
| Name | Description | Used for index |
|---|---|---|
| Name | Specifies the index name. | All types |
| Description | Specifies the index description. Click OK to save the description or Cancel to discard the changes. |
All types |
| Index Type | Indicates the index type for the column. | All types |
| Index columns grid | Defines properties of the index columns. | Clustered Nonclustered Primary XML Spatial |
| Included columns grid | Defines properties of the included columns. | Nonclustered |
| Primary XML Index | Indicates a primary XML index for the secondary index. | Secondary XML |
| Secondary XML Index Type | Indicates the types of secondary indexes: PATH, VALUE, and PROPERTY. |
Secondary XML |
Index columns
The following table describes the properties in the index columns grid.
| Name | Description | Used for index |
|---|---|---|
| Name | Specifies the index column. | Clustered Nonclustered Spatial Primary XML |
| Data Type | Indicates the data type of the column. | Clustered Nonclustered Spatial Primary XML |
| Not Null | Indicates whether the column is NOT NULL. |
Clustered Nonclustered Spatial Primary XML |
| Sort Order | Sorts indexed columns in ascending or descending order. | Clustered Nonclustered |
| Remove | Removes the selected column. Alternatively, select Remove Column from the shortcut menu. Shortcut: Ctrl+Del |
Clustered Nonclustered Spatial Primary XML |
| Move up | Moves the selected column up. Alternatively, select Move Column Up from the shortcut menu. Shortcut: Ctrl+Up |
Clustered Nonclustered Spatial Primary XML |
| Move down | Moves the selected column down. Alternatively, select Move Column Down from the shortcut menu. Shortcut: Ctrl+Down |
Clustered Nonclustered Spatial Primary XML |
Included columns
The following table describes the properties for included columns.
| Name | Description | Used for |
|---|---|---|
| Name | Specifies the included column. | Nonclustered |
| Data Type | Indicates a data type of the column. | Nonclustered |
| Not Null | Indicates whether the column is NOT NULL. |
Nonclustered |
| Remove | Removes the selected column. Alternatively, select Remove Column from the shortcut menu. Shortcut: Ctrl+Del |
Nonclustered |
| Move up | Moves the selected column up. Alternatively, select Move Column Up from the shortcut menu. Shortcut: Ctrl+Up |
Nonclustered |
| Move down | Moves the selected column down. Alternatively, select Move Column Down from the shortcut menu. Shortcut: Ctrl+Down |
Nonclustered |
Options
The following table describes index options.
| Name | Description | Used for |
|---|---|---|
| Auto recompute statistics | Automatically updates the statistics as data changes. | Clustered Nonclustered Spatial |
| Ignore duplicate values | Ignores duplicate values instead of causing an error. | Clustered Nonclustered |
| Allow page locks | Locks entire pages of data when accessing the index. When the option is turned off, SQL Server doesn’t acquire page locks on the index and uses row-level or table-level locks instead. Note: This may lead to blocking or deadlocks if multiple users try to access rows on the same page. |
Clustered Nonclustered Primary XML Secondary XML Spatial |
| Allow row locks | Locks individual rows in the index or table. When the option is turned off, SQL Server cannot acquire row-level locks for the index and uses page-level or table-level locks instead. Note: This may lead to blocking or deadlocks if multiple users try to access rows on the same page. |
Clustered Nonclustered Primary XML Secondary XML Spatial |
| Maximum degree of parallelism | Controls how many CPU cores SQL Server can use in parallel to build or rebuild the index. | All types |
| Fill factor | Specifies the percentage of space to fill on each leaf-level page with data, reserving the remaining space for future inserts or updates. | Clustered Nonclustered Primary XML Secondary XML Spatial |
| Pad Index | Applies the FILLFACTOR option to the intermediate-level pages of the index. When the option is turned off, SQL Server fills the intermediate index pages almost fully, with minimal space left for one additional maximum-sized row. |
Clustered Nonclustered Primary XML Secondary XML Spatial |
| Sort in tempdb | Uses the tempdb system database for sorting during index creation, after which the completed index is written to the target database. When the option is turned off, SQL Server performs the sort operation within the user database. |
Clustered Nonclustered Primary XML Secondary XML Spatial |
| Expression | Specifies a WHERE clause to include only specific rows. |
Clustered Nonclustered |
| Cells per Object | Defines the maximum number of cells that tessellation can count per object. | Spatial |
| Tessellation Scheme | Identifies a tessellation scheme for the index. | Spatial |
| X-min | Identifies an x-coordinate of the lower-left corner of the bounding box. | Spatial |
| Y-min | Identifies a y-coordinate of the lower-left corner of the bounding box. | Spatial |
| X-max | Identifies an x-coordinate of the upper-right corner of the bounding box. | Spatial |
| Y-max | Identifies a y-coordinate of the upper-right corner of the bounding box. | Spatial |
| Level 1 | Represents the coarsest grid cells (lowest resolution). | Spatial |
| Level 2 | Represents the medium grid cells. | Spatial |
| Level 3 | Represents the finer grid cells. | Spatial |
| Level 4 | Represents the finest grid cells. | Spatial |
Storage
The following table describes storage properties.
| Name | Description | Used for |
|---|---|---|
| Regular data space | Specifies the filegroup where the main table data will be physically stored. To update the list of filegroups, click  . Note: PRIMARY is the default filegroup created with the database unless otherwise specified.Shortcut: Ctrl+R |
Clustered Nonclustered Spatial Clustered columnstore Nonclustered columnstore |
| Partition column | Defines a column that splits the data into multiple partitions, each stored in a different filegroup. When the property is turned off, partitioning is not configured for this table. |
Clustered Nonclustered Spatial Clustered columnstore Nonclustered columnstore |
| Filestream data space | Defines where SQL Server will store FILESTREAM-enabled columns. When it is set to <Default>, it implies that FILESTREAM data (binary large objects, such as documents or images) will use the default storage settings. To update the list of filegroups, click .Shortcut: Ctrl+R |
Clustered Nonclustered Spatial Clustered columnstore Nonclustered columnstore |
| Text/Image filegroup | Controls where to store TEXT, NTEXT, or IMAGE data types.To update the list of filegroups, click .Shortcut: Ctrl+R |
Clustered Nonclustered Spatial Clustered columnstore Nonclustered columnstore |
Fragmentation
The fragmentation settings are available only for clustered and nonclustered indexes. They determine how data is distributed and stored in a database based on the index structure. They include size, leaf-level rows, average row size, maximum and minimum row size.
Usage Statistics
Usage statistics are available only for clustered and nonclustered indexes. It lets you monitor operations, such as reads, writes, or page I/O used by the index in the database.
Save the changes
An asterisk (*) on the Table Designer tab indicates unsaved changes.
To save and apply them, in the bottom panel, select Apply Changes.
Note
To discard all changes made since Table Designer was opened or last saved, on the standard toolbar, click
. The object is reloaded from the server, and all unsaved changes are permanently lost. You can’t redo changes after an undo operation for database objects.